Agent architecture
Stop Making AI Think About What Software Already Knows
The next big improvement in AI agents might not come from smarter models. It might come from giving them less to think about.
Imagine you're building an AI agent that works across APIs, databases, and business systems. It needs to retrieve facts, remember previous actions, check permissions, make decisions, and reliably complete a task.
You give it a powerful reasoning model and a detailed prompt: "Be careful. Verify everything. Don't invent facts. Don't repeat actions."
But why ask an AI to reason about things ordinary software can check?
Whether an email address is on a suppression list isn't a creative problem. Neither is checking a unique identifier, validating required fields, or enforcing a permission. We've been writing reliable software for these jobs for decades.
Yet we increasingly ask expensive AI models to handle them through natural-language reasoning. I think there's a better way.
We're using reasoning where we should be using software
Modern models can interpret ambiguous instructions, plan workflows, and make useful judgments. That's where they're valuable.
But a long-running agent may also need to remember which records it processed, consult a database, enforce restrictions, calculate costs, validate data, and verify that an external action actually happened.
Some of those tasks require judgment. Many don't.
When the model is responsible for everything, it must repeatedly reconstruct state and reinterpret rules from its context. Even capable models can make mistakes. More reasoning doesn't turn a language model into a transactional database or a permission system.
A model shouldn't have to remember a rule that software can enforce.
What changes when we give agents better tools?
This is where APIs, the Model Context Protocol (MCP), and ChatGPT apps become interesting.
MCP standardizes how an AI system discovers and calls external capabilities. But the important part isn't the protocol: it's what happens behind the tool.
Instead of manually inspecting a hundred records for duplicates, an agent can invoke a database-backed duplicate checker.
Instead of remembering who must not be contacted, it can ask a suppression API that enforces the restriction.
Instead of hoping its JSON is correct, it can run a schema validator.
Instead of assuming an external action succeeded, it can read back the resulting state and check an idempotency key.
The model still decides what to accomplish. It simply doesn't need to simulate all the machinery used to accomplish it.
We move predictable work out of probabilistic reasoning and into software with explicit rules.
A practical example: Five sales leads
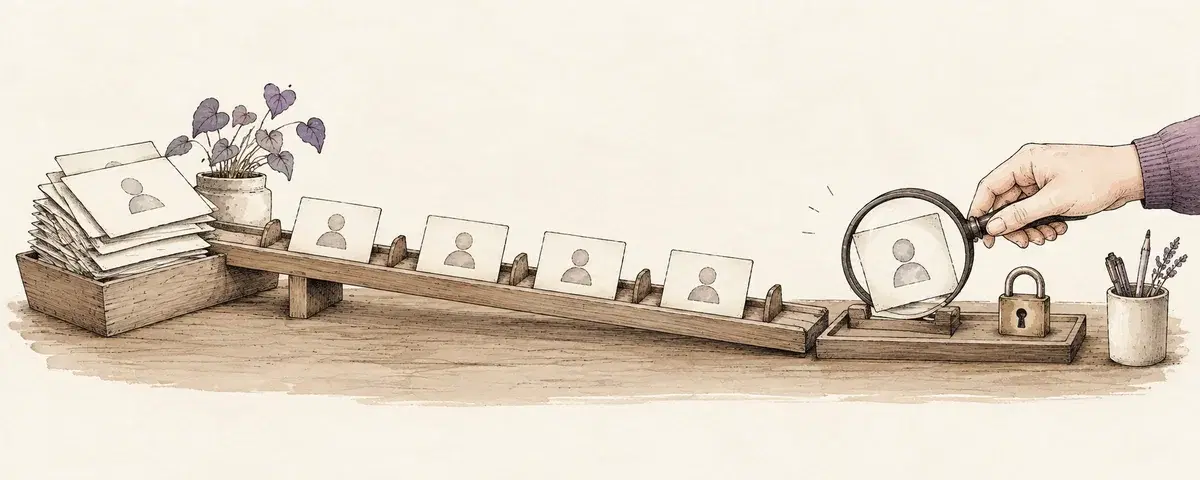
Suppose I ask an agent: "Find five promising companies, identify the right people, and prepare personalized outreach."
Approach A: The model handles everything.
The agent searches, reads company pages, compares employee counts, checks titles, remembers past leads, examines restrictions, drafts messages, and reviews its own work. If it misses a duplicate, fabricates a claim, or overlooks a restriction, we may only discover the problem later.
We can increase reasoning effort and add instructions to double-check. But we're still asking the same system to perform the work and judge its own correctness.
Approach B: Give the model specialized tools.
- Research: The agent gathers prospects and supporting evidence.
- Validate: Software checks record structure, duplicates, restrictions, and explicit rules.
- Review: A specialized tool reports supported claims, uncertainty, and gaps.
- Decide: The model evaluates fit, decision-maker authority, and whether there's a credible reason to reach out.
- Approve: Application permissions and human approval protect sensitive actions.
The model still handles ambiguity and conflicting evidence. But routine checks no longer depend on its reasoning. A specific validation failure can trigger a specific correction instead of another full self-review.
Here's the division of labor in a typical tool-assisted workflow:
- User goal
- Agent: interpret and research
- Tools: retrieve state and validate rules
- Evidence sufficient?No or uncertainAgent: investigate or escalate↩ Tools: retrieve state and validate rules
- YesAgent: propose next step
- Application permissions and approval when needed
- Execute action and verify outcome
The important part is the boundary: the model can recommend a step, but the application must enforce permissions and verify critical state changes.
Could better tools mean cheaper reasoning?
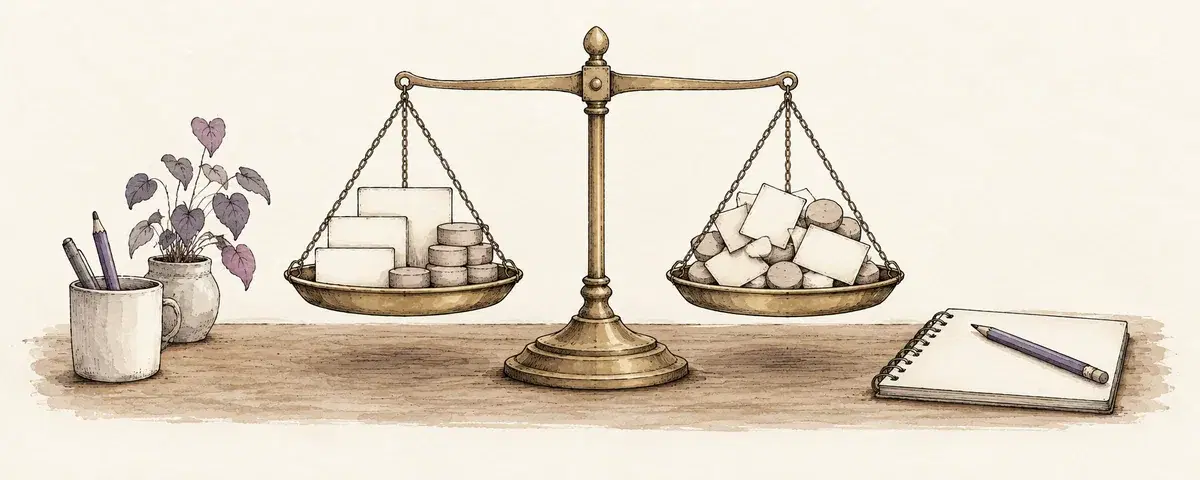
Potentially.
Depending on the model, higher reasoning-effort settings can increase token use, runtime, and cost. A complicated workflow may seem to require Max reasoning—but what if much of that complexity comes from work software could do directly?
Compare two configurations:
Configuration 1: Max reasoning, with the model handling decisions and routine validation.
Configuration 2: Medium reasoning, with specialized tools performing routine checks.
Could the second produce results that are just as reliable, for less money?
That's a hypothesis, not a measured conclusion. Tools have their own API fees, latency, failure modes, and orchestration overhead. Some difficult cases genuinely benefit from more reasoning.
The right question isn't whether Medium is always as good as Max. It's whether well-designed tools reduce the reasoning budget needed to reach the same quality and safety standard.
MCP doesn't automatically make anything deterministic
MCP is a connection protocol, not a guarantee that the tool behind it is reliable.
One tool might query a database. Another might run a deterministic validator. A third might call another uncertain language model. They can all use the same protocol.
Tools can return stale data, apply the wrong rule, or fail. Retrieved pages and tool results may also carry prompt-injection attempts, which must not be treated as trusted instructions. So moving work into tools doesn't mean trusting them blindly.
We need explicit contracts, clear errors, evidence of what was actually checked, and meaningful permission boundaries. A validator should say what's known and what remains uncertain.
The goal isn't to replace one black box with another. It's to make the system easier to verify.
How would we prove this works?
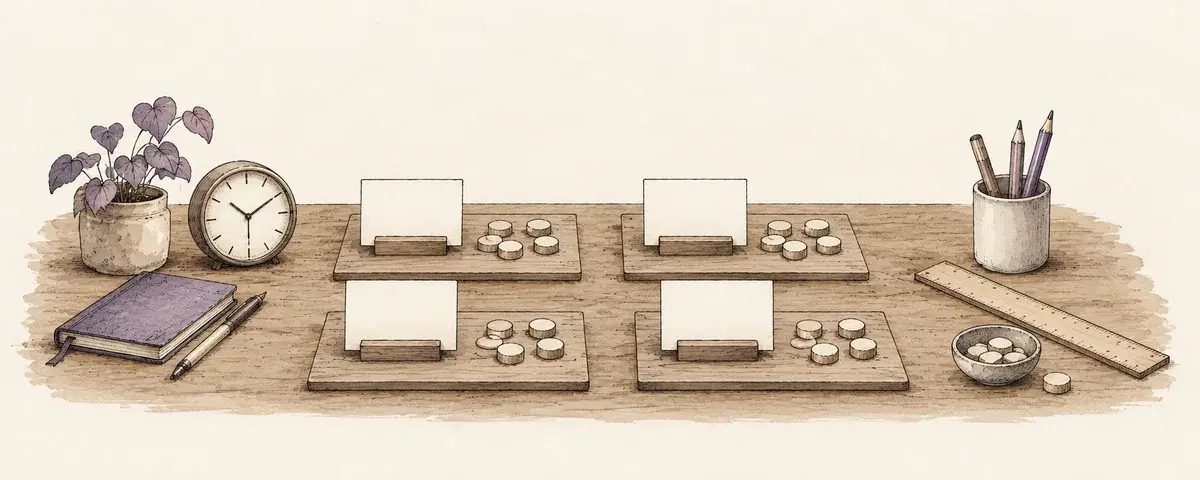
Test the same underlying model under four configurations:
| Configuration | Reasoning | Specialized tools |
|---|---|---|
| A | Max | No |
| B | Medium | No |
| C | Max | Yes |
| D | Medium | Yes |
Keep tasks, tool access, and initial conditions comparable. Use independent acceptance criteria, isolated starting state, and repeated runs. The supported reasoning-effort settings depend on the model being evaluated.
Measure correct completion rate, serious mistakes, retries, human corrections, wall-clock time, and total costs including external tools.
A tool-assisted agent might use fewer reasoning tokens yet cost more overall. So the metric that matters is total cost per correctly completed, safe task, not just token spending.
In a sales workflow, that could mean cost per independently accepted lead or outreach draft—not merely cost per generated lead.
If Medium with tools proves sufficient for routine cases but Max is better on difficult ones, we could use lower reasoning by default and escalate when necessary. But the experiment must establish that, rather than assuming it.
The broader opportunity
The same principle applies far beyond sales.
A coding agent should run tests and type checkers rather than merely claim that its code works. A financial agent should use exact calculations. A research agent should retrieve actual source data. An operations agent should query system state instead of assuming commands succeeded.
The model is most valuable when interpretation and judgment are needed. For the rest, use the most reliable mechanism available—sometimes a database, a validator, another model, or a human.
I'm also exploring this division of labor with Meetlane, a lead-review tool, but the architectural question is much larger than any one product.
The smartest agent might be the one that reasons less
There's a tendency to solve agent reliability problems by asking models to think harder: use Max, add another verification prompt, and review the answer again.
Sometimes that's the right choice. But it shouldn't be the only choice.
When a problem has a precise, testable solution, ask whether it belongs inside the model's reasoning process at all.
Let software enforce the guarantees it can actually enforce. Let models handle ambiguity. Let humans control consequential decisions. Then measure whether the combination is cheaper, faster, and more reliable.
Maybe the next breakthrough in practical AI agents won't be getting them to think harder. Maybe it'll be getting them to stop thinking about things they don't need to.
Further reading
- Model Context Protocol — Tools specification: what tool discovery and invocation standardize, and what they do not.
- OpenAI — Build with the Apps SDK: how ChatGPT apps expose app logic and interfaces through MCP.
- OpenAI — Reasoning models and reasoning effort: reasoning-effort controls and their quality, speed, and cost tradeoffs.
The Max/Medium comparison in this article is a proposed experiment, not a claim of measured savings.